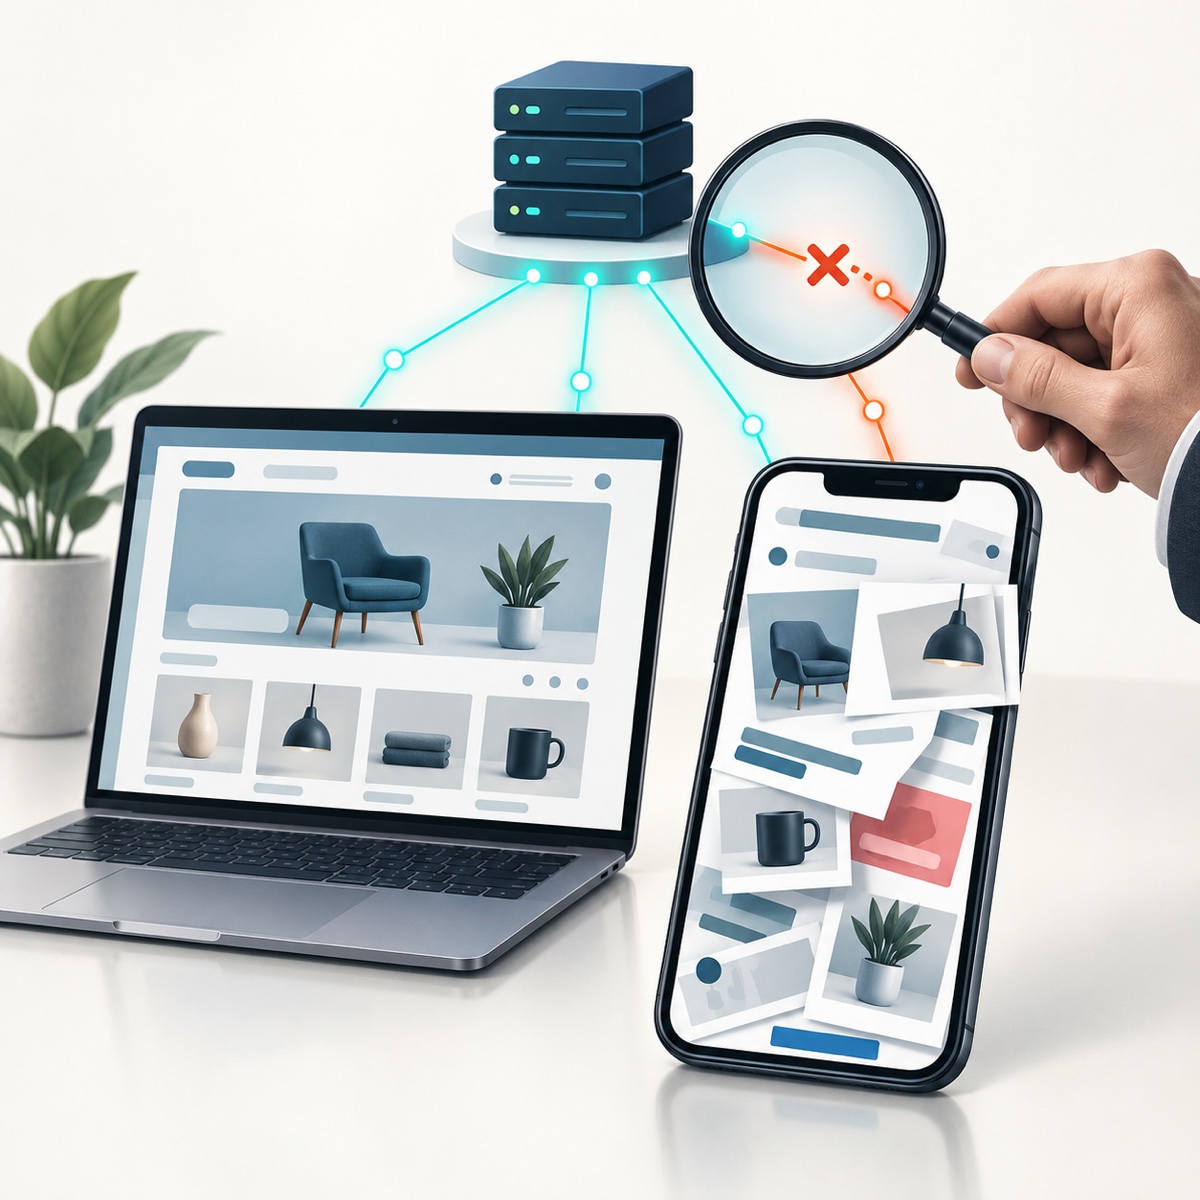
A website can be online while some customers cannot use it. A CDN misconfiguration can leave mobile visitors facing overlapping text, broken navigation and missing styling, even when another browser looks normal. The business exposure includes interrupted purchases, wasted advertising spend and damaged trust. An incident investigated on 10–11 October 2026 illustrates why professional website management must check what customers actually experience, as well as whether a server responds.
Need a website reliability review? Contact our team · bali@birudaun.net · +62 361 4748157
The first impression is part of the sale
A customer follows an advertisement, opens a product page and finds a confusing jumble of links. The business may still be paying for that visit. Its products may be available and its payment system healthy. But the journey towards a purchase has already been disrupted.
Visitors see the brand’s website, not the delivery infrastructure behind it. A technical failure can therefore become a question about the business itself: is this company dependable, and is it sensible to buy here? The same uncertainty can affect enquiries and bookings.
That is why a fault affecting only part of an audience deserves attention. Overall uptime and aggregate sales figures can conceal a poor experience for a commercially important customer group.
An incident that looked different on different screens
Records from the investigation describe pages that lost their intended styling in Safari on iPhone and macOS. Text overlapped and navigation became difficult to use. Meanwhile, the recorded Chromium tests loaded the stylesheets and displayed the page correctly.
Cleanup continued into the following day, with checks indicating that some endpoints had improved while others still needed attention. Those checks were snapshots of particular requests, not proof that every affected page had recovered.
The records identify a concrete delivery defect: stylesheet responses reportedly contained a connection-specific header that does not belong in HTTP/2 or HTTP/3. The evidence supports investigating that defect as a cause of the Safari failures. It does not include a complete capture of Safari’s failing requests that would establish every step of the sequence.
How one response header can disrupt a storefront
CSS files tell a browser how to arrange and style a page. A content delivery network, or CDN, commonly serves these files through edge servers near visitors. If a browser cannot accept a stylesheet response, the HTML may still arrive, leaving content visible without its intended presentation.
The reported response included:
upgrade: h2,h2cThis is an illustrative excerpt of the reported defect, not a configuration recommendation. The Upgrade field belongs to HTTP/1.1 protocol-switching mechanisms. It must not be carried into HTTP/2 or HTTP/3 responses. Both standards require intermediaries to remove connection-specific fields when translating HTTP/1.x messages. See the HTTP/2 requirements and HTTP/3 requirements.
The separate Alt-Svc header can legitimately advertise HTTP/3 availability. Finding it alongside a failure does not establish an HTTP/3 fault. The important question is which protocol was actually negotiated and whether that response complied with its rules.
Why another browser—or a reload—can hide the problem
MDN documents that Safari rejects HTTP/2 responses containing prohibited connection-specific headers, while Chrome and Firefox ignore them. That helps explain how the same delivery defect can produce different visible results.
It does not justify declaring every other visitor unaffected. Browser versions, connections and cached responses can differ. A successful test is evidence about that test, rather than a guarantee for the whole audience.
Another reported observation matters for customers: reloading can restore the page on current iOS. The available evidence does not establish whether this recovery involves caching, a different connection, a different edge response or another mechanism. A browser user-agent change alone cannot reproduce Safari’s behavior.
Customers should not have to discover a reload workaround. Recovery needs to be checked on a fresh first visit as well as a repeat visit.
Revenue and trust need their own measurements
An unusable page can interrupt product discovery, make navigation confusing and discourage a customer from continuing. Advertising may keep sending paid traffic to the affected experience throughout the incident.
The incident records do not quantify lost revenue. Understanding the value of the affected audience requires business data, rather than assumptions about the purchasing power associated with a particular device. Teams should examine their own evidence: conversion rates, abandoned journeys, enquiries and revenue by browser and device before, during and after the problem.
Look at meaningful audience segments alongside totals. A stable overall conversion rate can coexist with a deterioration in one group. Interpretation also needs care: campaign changes, traffic quality and normal daily variation can affect the same figures.
What this means for technical SEO
Search engines need access to the resources required to understand and render a page. Google’s rendering guidance explains how crawling, rendering and indexing work together. Reliable delivery supports that process and the experience of people who arrive from search.
However, a Safari failure does not prove that a search engine encountered the same failure. Nothing in this incident record demonstrates an indexing loss or ranking decline. Those claims would require separate evidence.
Technical teams should check resource accessibility and rendered output in search inspection tools. They should also assess real visitor experience. Google’s page-experience guidance makes clear that a good result involves more than a single score. A healthy-looking dashboard cannot substitute for a usable customer journey.
What professional oversight adds
Effective incident handling connects a visitor’s symptoms to reproducible technical evidence. A useful diagnostic checklist is:
- Test fresh visits on real iPhone and macOS Safari sessions, alongside other browsers.
- Inspect actual failing CSS requests, their response headers and the negotiated HTTP protocol; a clean homepage or CDN root response is insufficient.
- Compare origin and edge behavior, including cache hits and misses, to locate where the invalid header enters the response.
- Correct the responsible configuration, invalidate affected cached responses where needed, and verify delivery again.
- Recheck important customer journeys across relevant devices and locations before declaring recovery.
The operational work continues after the immediate correction. Clear escalation, a rollback plan, staged changes and automated checks for prohibited headers help reduce recurrence. Monitoring should cover rendered pages and essential assets, not just the homepage status code.
For management, the useful questions are concrete: who owns the incident, which customers may be affected, what mitigation is available, and what evidence will demonstrate recovery? A provider’s assurance that a change is complete should lead to independent checks of the affected experience. Keeping a concise record of symptoms, timestamps, actions and retest results gives the business a basis for deciding when normal operations can resume with confidence.
These responsibilities help explain the value of professionally managed website hosting. Skilled teams need to understand protocols, caching and browser behavior—and communicate what is confirmed, what remains uncertain and what has been retested.
Protect the customer’s first visit
The lesson is straightforward: availability must be judged from the customer’s side of the screen. Professional technical oversight helps a business detect selective failures, coordinate a lasting correction and protect the confidence on which enquiries and sales depend.
Review your website’s reliability before customers have to report a problem. Contact our team · bali@birudaun.net · +62 361 4748157